Harness 工程:在智能体优先的世界中运用 Codex
By Ryan Lopopolo, Member of the Technical Staff
作者:Ryan Lopopolo,技术团队成员
Over the past five months, our team has been running an experiment: building and shipping an internal beta of a software product with 0 lines of manually-written code.
过去五个月里,我们团队一直在做一项实验:用 0 行手写代码 构建并交付一个软件产品的内测版本。
The product has internal daily users and external alpha testers. It ships, deploys, breaks, and gets fixed. What’s different is that every line of code—application logic, tests, CI configuration, documentation, observability, and internal tooling—has been written by Codex. We estimate that we built this in about 1/10th the time it would have taken to write the code by hand.
这个产品有内部日常用户,也有外部 alpha 测试者。它会发布、部署、出错,也会被修复。不同之处在于,每一行代码——应用逻辑、测试、CI 配置、文档、可观测性和内部工具——都是由 Codex 编写的。我们估计,完成它所用的时间大约只有手写代码的 1/10。
Humans steer. Agents execute.
人类掌舵,智能体执行。
We intentionally chose this constraint so we would build what was necessary to increase engineering velocity by orders of magnitude. We had weeks to ship what ended up being a million lines of code. To do that, we needed to understand what changes when a software engineering team’s primary job is no longer to write code, but to design environments, specify intent, and build feedback loops that allow Codex agents to do reliable work.
我们有意选择这一约束,是为了构建出把工程速度提升几个数量级所必需的一切。我们只有几周时间,却要交付一个最终达到百万行代码的产品。要做到这一点,我们需要弄清楚:当一个软件工程团队的首要工作不再是写代码,而是设计环境、明确意图,并构建让 Codex 智能体可靠工作的反馈回路时,会发生哪些变化。
This post is about what we learned by building a brand new product with a team of agents—what broke, what compounded, and how to maximize our one truly scarce resource: human time and attention.
本文讲述的是我们从“用一支智能体团队从零构建全新产品”中学到的东西——什么出了问题,什么产生了复利,以及如何最大化我们唯一真正稀缺的资源:人类的时间与注意力。
We started with an empty git repository
从空的 git 仓库开始
The first commit to an empty repository landed in late August 2025.
2025 年 8 月下旬,我们向一个空仓库提交了第一个 commit。
The initial scaffold—repository structure, CI configuration, formatting rules, package manager setup, and application framework—was generated by Codex CLI using GPT‑5, guided by a small set of existing templates. Even the initial AGENTS.md file that directs agents how to work in the repository was itself written by Codex.
初始脚手架——仓库结构、CI 配置、格式化规则、包管理器设置和应用框架——由 Codex CLI 使用 GPT‑5 生成,并以少量现有模板作为指引。甚至连指导智能体如何在仓库中工作的初始 AGENTS.md 文件,本身也是由 Codex 编写的。
There was no pre-existing human-written code to anchor the system. From the beginning, the repository was shaped by the agent.
没有任何预先存在的人工代码作为系统的锚点。从一开始,这个仓库就是由智能体塑造的。
Five months later, the repository contains on the order of a million lines of code across application logic, infrastructure, tooling, documentation, and internal developer utilities. Over that period, roughly 1,500 pull requests have been opened and merged with a small team of just three engineers driving Codex. This translates to an average throughput of 3.5 PRs per engineer per day, and surprisingly the throughput has increased as the team has grown to now seven engineers. Importantly, this wasn’t output for output’s sake: the product has been used by hundreds of users internally, including daily internal power users.
五个月后,仓库中已包含约一百万行代码,涵盖应用逻辑、基础设施、工具、文档和内部开发者实用工具。在此期间,仅由三名工程师驱动 Codex,就创建并合并了约 1,500 个 pull request。这相当于每位工程师每天平均 3.5 个 PR 的吞吐量;而令人意外的是,当团队扩大到七名工程师后,吞吐量反而上升了。重要的是,这并不是为了产出而产出:该产品已被内部数百名用户使用,其中包括每天使用它的内部重度用户。
Throughout the development process, humans never directly contributed any code. This became a core philosophy for the team: no manually-written code.
在整个开发过程中,人类从未直接贡献任何代码。这成了团队的核心信条:不写任何手写代码。
Redefining the role of the engineer
重新定义工程师的角色
The lack of hands-on human coding introduced a different kind of engineering work, focused on systems, scaffolding, and leverage.
人类不再亲自写代码,这催生了另一种类型的工程工作:聚焦于系统、脚手架和杠杆效应。
Early progress was slower than we expected, not because Codex was incapable, but because the environment was underspecified. The agent lacked the tools, abstractions, and internal structure required to make progress toward high-level goals. The primary job of our engineering team became enabling the agents to do useful work.
早期进展比我们预期的慢,原因不是 Codex 能力不足,而是环境定义得不够清楚。智能体缺乏朝着高层目标推进所需的工具、抽象和内部结构。我们工程团队的首要任务,变成了让智能体能够做有用的工作。
In practice, this meant working depth-first: breaking down larger goals into smaller building blocks (design, code, review, test, etc), prompting the agent to construct those blocks, and using them to unlock more complex tasks. When something failed, the fix was almost never “try harder.” Because the only way to make progress was to get Codex to do the work, human engineers always stepped into the task and asked: “what capability is missing, and how do we make it both legible and enforceable for the agent?”
在实践中,这意味着深度优先地工作:把更大的目标拆解为更小的构建块(设计、编码、评审、测试等),提示智能体构建这些块,再用它们解锁更复杂的任务。当某件事失败时,解决办法几乎从来不是“再努力一点”。因为推进工作的唯一途径是让 Codex 去做,人类工程师总是会深入任务并追问:“缺少什么能力?我们如何让这个能力对智能体来说既可理解又可强制执行?”
Humans interact with the system almost entirely through prompts: an engineer describes a task, runs the agent, and allows it to open a pull request. To drive a PR to completion, we instruct Codex to review its own changes locally, request additional specific agent reviews both locally and in the cloud, respond to any human or agent given feedback, and iterate in a loop until all agent reviewers are satisfied (effectively this is a Ralph Wiggum Loop). Codex uses our standard development tools directly (gh, local scripts, and repository-embedded skills) to gather context without humans copying and pasting into the CLI.
人类几乎完全通过提示词与系统交互:工程师描述一项任务,运行智能体,并允许它发起 pull request。为了把一个 PR 推进到完成,我们会指示 Codex 在本地评审自己的改动,在本地和云端请求额外的特定智能体评审,回应任何人类或智能体给出的反馈,并循环迭代,直到所有智能体评审者都满意(实际上这就是一个 Ralph Wiggum Loop)。Codex 直接使用我们的标准开发工具(gh、本地脚本和仓库内置的技能)来收集上下文,无需人类把内容复制粘贴到 CLI 中。
Humans may review pull requests, but aren’t required to. Over time, we’ve pushed almost all review effort towards being handled agent-to-agent.
人类可以评审 pull request,但不是必须的。随着时间推移,我们几乎把所有的评审工作都交给了智能体与智能体之间处理。
Increasing application legibility
提升应用的可理解性
As code throughput increased, our bottleneck became human QA capacity. Because the fixed constraint has been human time and attention, we’ve worked to add more capabilities to the agent by making things like the application UI, logs, and app metrics themselves directly legible to Codex.
随着代码吞吐量上升,我们的瓶颈变成了人类的 QA 能力。由于固定不变的约束始终是人的时间与注意力,我们努力为智能体增加能力——方式就是让应用 UI、日志和应用指标本身能够被 Codex 直接理解。
For example, we made the app bootable per git worktree, so Codex could launch and drive one instance per change. We also wired the Chrome DevTools Protocol into the agent runtime and created skills for working with DOM snapshots, screenshots, and navigation. This enabled Codex to reproduce bugs, validate fixes, and reason about UI behavior directly.
例如,我们让应用可以按 git worktree 分别启动,这样 Codex 就能为每个改动启动并驱动一个实例。我们还将 Chrome DevTools Protocol 接入智能体运行时,并创建了处理 DOM 快照、截图和导航的技能。这使 Codex 能够复现缺陷、验证修复,并直接推理 UI 行为。
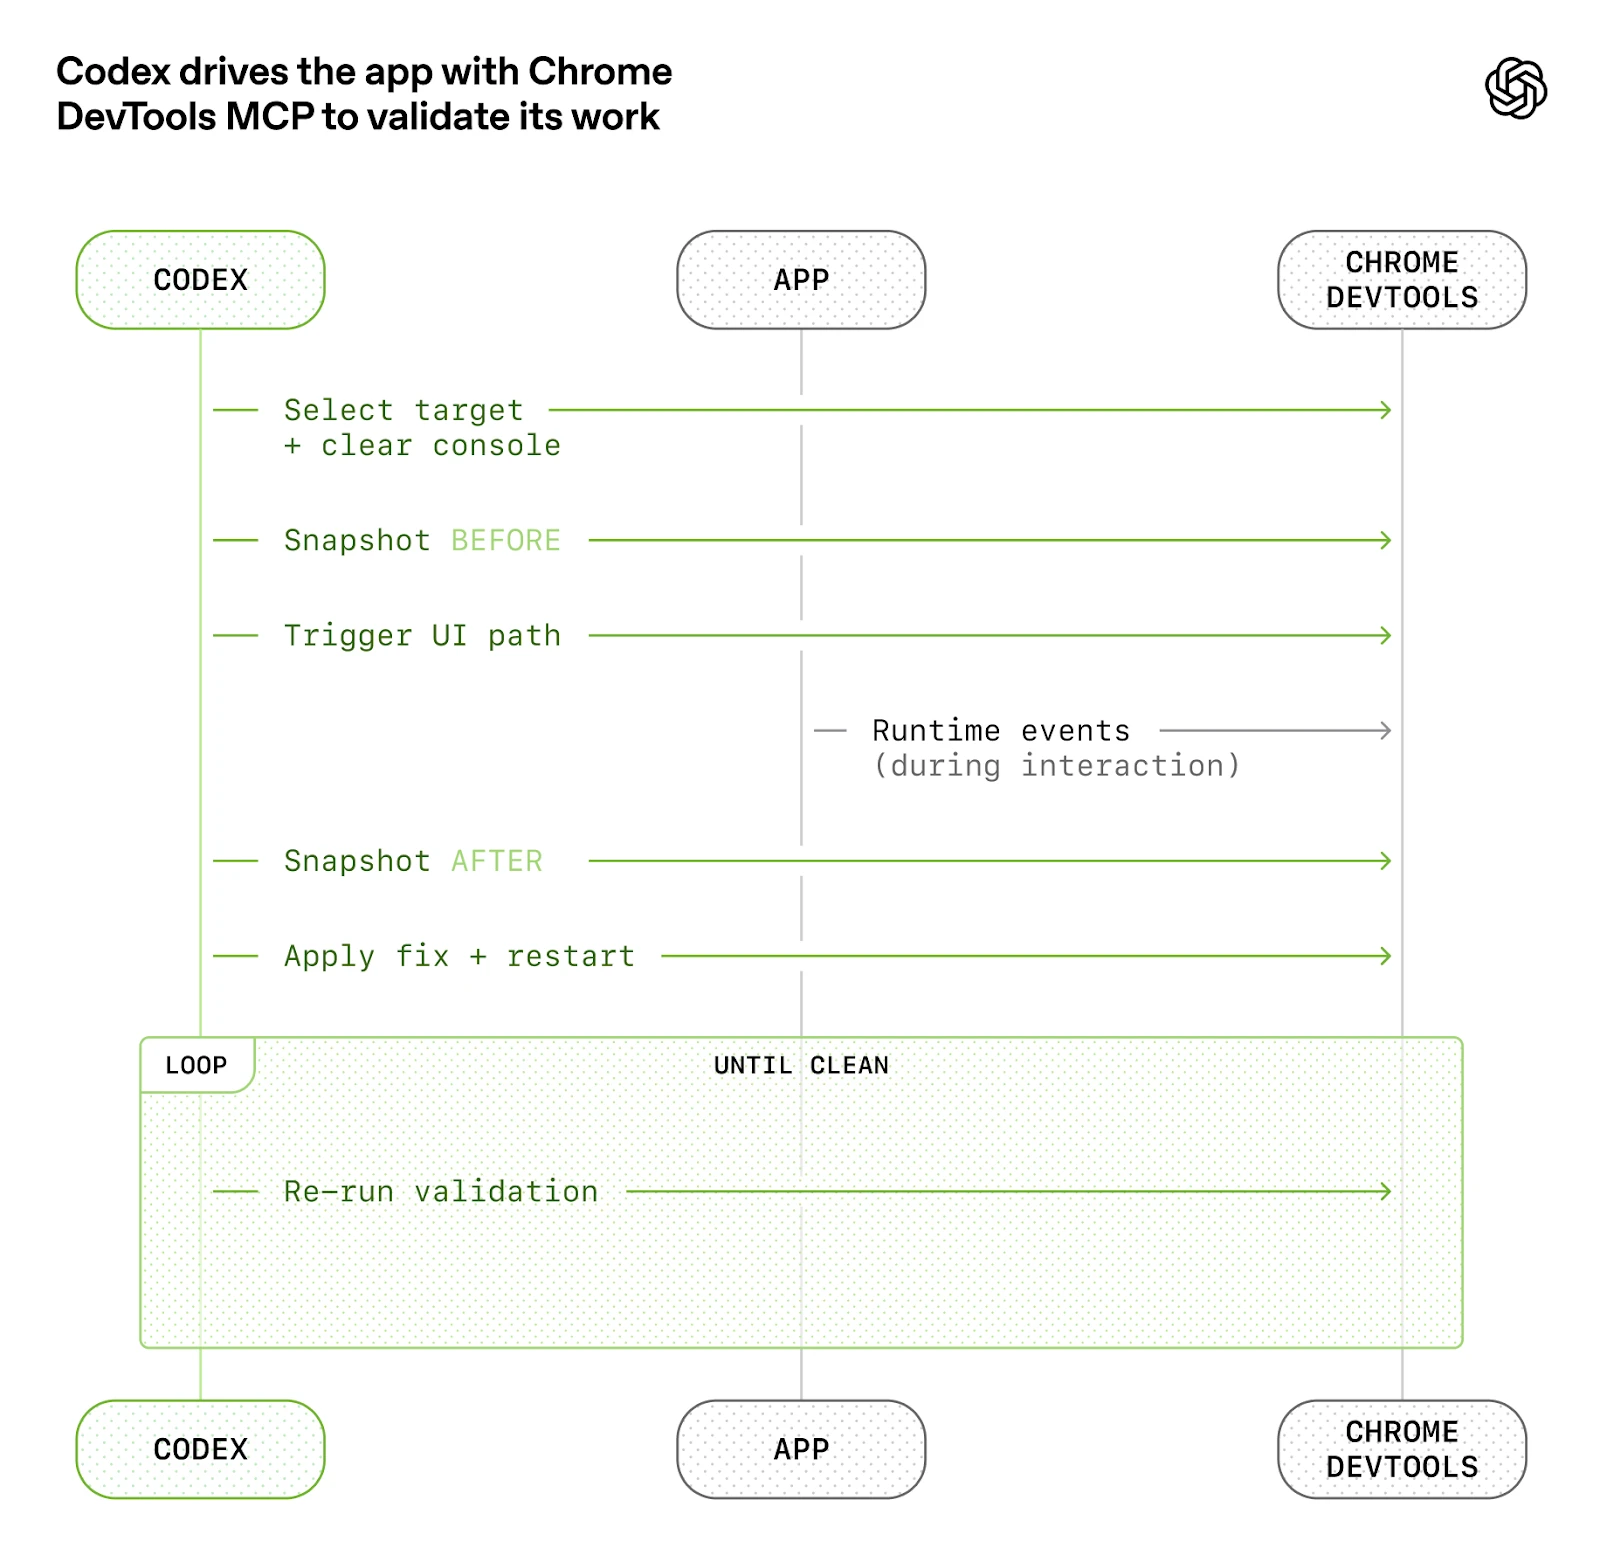
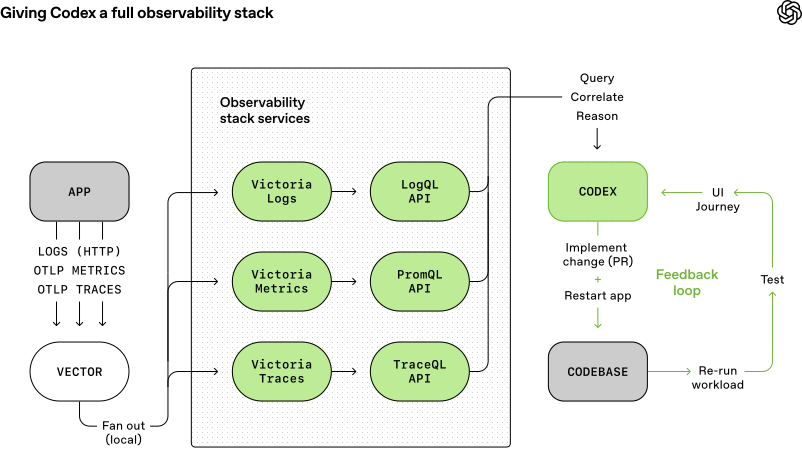
We did the same for observability tooling. Logs, metrics, and traces are exposed to Codex via a local observability stack that’s ephemeral for any given worktree. Codex works on a fully isolated version of that app—including its logs and metrics, which get torn down once that task is complete. Agents can query logs with LogQL and metrics with PromQL. With this context available, prompts like “ensure service startup completes in under 800ms” or “no span in these four critical user journeys exceeds two seconds” become tractable.
我们对可观测性工具也做了同样的事。日志、指标和链路追踪通过一个本地可观测性栈暴露给 Codex,该栈对任意 worktree 都是临时的。Codex 处理的是应用的完全隔离版本——包括其日志和指标,任务完成后它们会被拆除。智能体可以用 LogQL 查询日志,用 PromQL 查询指标。有了这些上下文,“确保服务启动在 800ms 内完成”或“这四条关键用户旅程中没有 span 超过两秒”这类提示就变得可行了。
We regularly see single Codex runs work on a single task for upwards of six hours (often while the humans are sleeping).
我们经常看到单次 Codex 运行在一个任务上持续工作六个小时以上(往往是在人类睡觉的时候)。
We made repository knowledge the system of record
我们把仓库知识作为唯一可信来源
Context management is one of the biggest challenges in making agents effective at large and complex tasks. One of the earliest lessons we learned was simple: give Codex a map, not a 1,000-page instruction manual.
上下文管理是让智能体在大型复杂任务中发挥作用的最大挑战之一。我们最早学到的教训很简单:给 Codex 一张地图,而不是一本 1,000 页的说明书。
We tried the “one big AGENTS.md” approach. It failed in predictable ways:
我们尝试过“一个大而全的 AGENTS.md”方案。它以一种可预期的方式失败了:
Context is a scarce resource. A giant instruction file crowds out the task, the code, and the relevant docs—so the agent either misses key constraints or starts optimizing for the wrong ones.
Too much guidance becomes non-guidance. When everything is “important,” nothing is. Agents end up pattern-matching locally instead of navigating intentionally.
It rots instantly. A monolithic manual turns into a graveyard of stale rules. Agents can’t tell what’s still true, humans stop maintaining it, and the file quietly becomes an attractive nuisance.
It’s hard to verify. A single blob doesn’t lend itself to mechanical checks (coverage, freshness, ownership, cross-links), so drift is inevitable.
上下文是稀缺资源。 一份巨大的指令文件会挤占任务、代码和相关文档的空间,于是智能体要么漏掉关键约束,要么开始朝着错误的约束做优化。
过度指导反而变成非指导。 当所有事情都“重要”时,就没有任何事情重要。智能体最终只是在局部做模式匹配,而不是有意识地进行导航。
它会立即腐坏。 一份单体式手册会变成过时规则的坟场。智能体分不清哪些规则仍然成立,人类也不再维护它,于是这个文件悄悄变成了一个诱人的麻烦。
它难以验证。 一整块文本无法进行机械化检查(覆盖率、新鲜度、归属、交叉链接),因此漂移不可避免。
So instead of treating AGENTS.md as the encyclopedia, we treat it as the table of contents.
因此,我们不把 AGENTS.md 当作百科全书,而是把它当作目录。
The repository’s knowledge base lives in a structured docs/ directory treated as the system of record. A short AGENTS.md (roughly 100 lines) is injected into context and serves primarily as a map, with pointers to deeper sources of truth elsewhere.
仓库的知识库位于结构化的 docs/ 目录中,被视为系统的唯一可信来源。一份简短的 AGENTS.md(约 100 行)会被注入上下文,主要充当一张地图,指向其他地方更深层的真相来源。
|
In-repository knowledge store layout.
仓库内知识库的布局。
Design documentation is catalogued and indexed, including verification status and a set of core beliefs that define agent-first operating principles. Architecture documentation provides a top-level map of domains and package layering. A quality document grades each product domain and architectural layer, tracking gaps over time.
设计文档被编目并建立索引,包括验证状态,以及一组定义智能体优先工作原则的核心信念。架构文档提供了领域与包分层的顶层地图。一份质量文档为每个产品领域和架构层评分,并持续跟踪差距。
Plans are treated as first-class artifacts. Ephemeral lightweight plans are used for small changes, while complex work is captured in execution plans with progress and decision logs that are checked into the repository. Active plans, completed plans, and known technical debt are all versioned and co-located, allowing agents to operate without relying on external context.
计划被视为一等公民产物。临时性的轻量计划用于小型改动,而复杂工作则记录为执行计划,其中包含进度日志和决策日志,并提交到仓库中。进行中的计划、已完成的计划和已知的技术债都纳入版本控制并与代码放在一起,使智能体无需依赖外部上下文即可工作。
This enables progressive disclosure: agents start with a small, stable entry point and are taught where to look next, rather than being overwhelmed up front.
这实现了渐进式披露:智能体从一个稳定的小入口开始,并被指引下一步该去哪里查找,而不是一开始就被大量信息淹没。
We enforce this mechanically. Dedicated linters and CI jobs validate that the knowledge base is up to date, cross-linked, and structured correctly. A recurring “doc-gardening” agent scans for stale or obsolete documentation that does not reflect the real code behavior and opens fix-up pull requests.
我们以机械化的方式落实这一点。专用的 linter 和 CI 任务会校验知识库是最新的、已交叉链接且结构正确。一个周期性的“文档园艺”智能体会扫描与真实代码行为不符的过时或废弃文档,并提交修复用的 pull request。
Agent legibility is the goal
目标是让智能体能够理解
As the codebase evolved, Codex’s framework for design decisions needed to evolve, too.
随着代码库的演进,Codex 做设计决策的框架也必须随之演进。
Because the repository is entirely agent-generated, it’s optimized first for Codex’s legibility. In the same way teams aim to improve navigability of their code for new engineering hires, our human engineers’ goal was making it possible for an agent to reason about the full business domain directly from the repository itself.
由于整个仓库完全由智能体生成,它首先是为 Codex 的可理解性 而优化的。就像团队会努力提升代码对新入职工程师的可导航性一样,我们人类工程师的目标,是让智能体能够直接从仓库本身推理整个业务领域。
From the agent’s point of view, anything it can’t access in-context while running effectively doesn’t exist. Knowledge that lives in Google Docs, chat threads, or people’s heads are not accessible to the system. Repository-local, versioned artifacts (e.g., code, markdown, schemas, executable plans) are all it can see.
从智能体的视角看,任何它在运行时无法在上下文中访问的东西,实际上都不存在。存在于 Google Docs、聊天线程或人们头脑中的知识,对系统来说都是不可访问的。仓库内本地的、带版本控制的产物(例如代码、markdown、schema、可执行计划)才是它所能看到的全部。
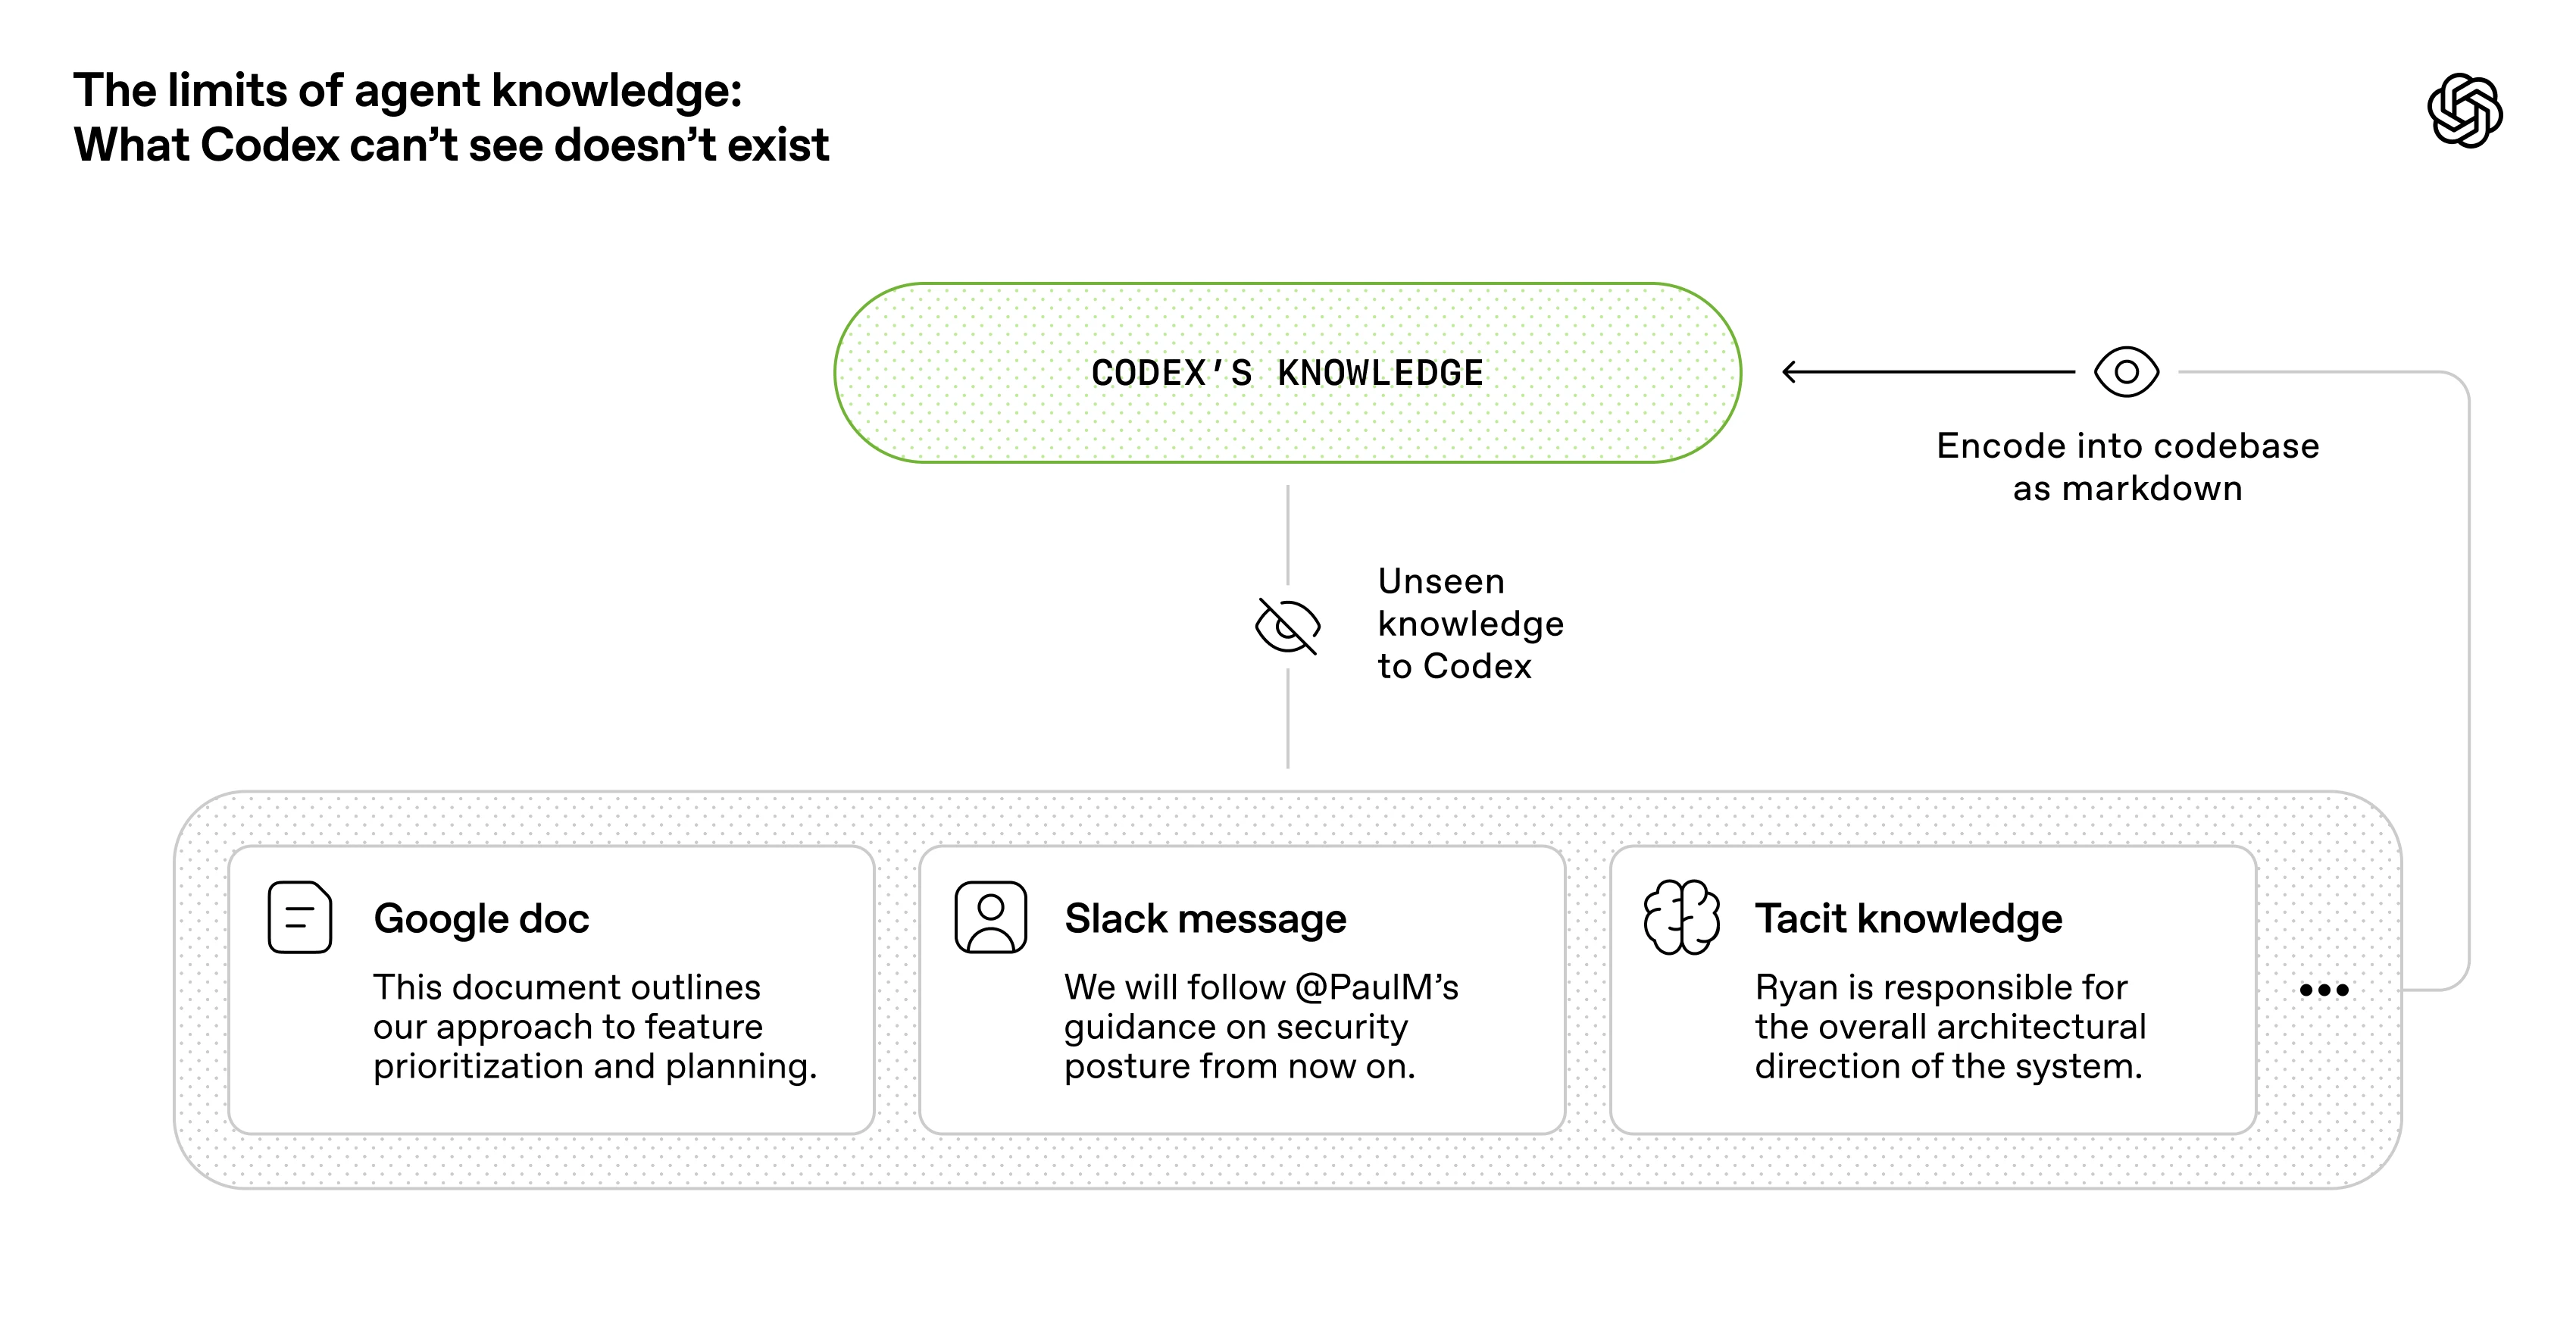
We learned that we needed to push more and more context into the repo over time. That Slack discussion that aligned the team on an architectural pattern? If it isn’t discoverable to the agent, it’s illegible in the same way it would be unknown to a new hire joining three months later.
我们学到,需要随着时间把越来越多的上下文推进仓库。那次让团队就某个架构模式达成一致的 Slack 讨论?如果智能体无法发现它,它就是不可理解的——就像三个月后入职的新人对此一无所知一样。
Giving Codex more context means organizing and exposing the right information so the agent can reason over it, rather than overwhelming it with ad-hoc instructions. In the same way you would onboard a new teammate on product principles, engineering norms, and team culture (emoji preferences included), giving the agent this information leads to better-aligned output.
给 Codex 更多上下文,意味着组织和暴露正确的信息,让智能体能够在其上推理,而不是用零散的临时指令淹没它。就像你会向新同事介绍产品原则、工程规范和团队文化(包括 emoji 偏好)一样,把这些信息交给智能体,会带来更对齐的输出。
This framing clarified many tradeoffs. We favored dependencies and abstractions that could be fully internalized and reasoned about in-repo. Technologies often described as “boring” tend to be easier for agents to model due to composability, api stability, and representation in the training set. In some cases, it was cheaper to have the agent reimplement subsets of functionality than to work around opaque upstream behavior from public libraries. For example, rather than pulling in a generic p-limit-style package, we implemented our own map-with-concurrency helper: it’s tightly integrated with our OpenTelemetry instrumentation, has 100% test coverage, and behaves exactly the way our runtime expects.
这一视角厘清了许多取舍。我们偏好那些能够被完全内化并在仓库内推理的依赖和抽象。通常被描述为“无聊”的技术,往往更容易被智能体建模,因为它们具备可组合性、API 稳定性和在训练集中的代表性。在某些情况下,让智能体重新实现部分功能,比绕过公共库中不透明的上游行为更划算。例如,我们没有引入一个通用的 p-limit 风格包,而是自己实现了并发映射辅助函数:它与我们的 OpenTelemetry 埋点紧密集成,测试覆盖率达到 100%,行为完全符合运行时的预期。
Pulling more of the system into a form the agent can inspect, validate, and modify directly increases leverage—not just for Codex, but for other agents (e.g. Aardvark) that are working on the codebase as well.
把系统中更多的部分转化为智能体可以直接检查、验证和修改的形式,会直接提升杠杆效应——不仅对 Codex 如此,对同样在这个代码库上工作的其他智能体(例如 Aardvark)也是如此。
Enforcing architecture and taste
强制执行架构与品味
Documentation alone doesn’t keep a fully agent-generated codebase coherent. By enforcing invariants, not micromanaging implementations, we let agents ship fast without undermining the foundation. For example, we require Codex to parse data shapes at the boundary, but are not prescriptive on how that happens (the model seems to like Zod, but we didn’t specify that specific library).
仅靠文档无法让一个完全由智能体生成的代码库保持一致性。我们通过强制不变量、而非微观管理实现方式,让智能体快速交付而不动摇地基。 例如,我们要求 Codex 在边界处解析数据形状,但对具体实现方式不做规定(模型似乎偏爱 Zod,但我们并没有指定这个库)。
Agents are most effective in environments with strict boundaries and predictable structure, so we built the application around a rigid architectural model. Each business domain is divided into a fixed set of layers, with strictly validated dependency directions and a limited set of permissible edges. These constraints are enforced mechanically via custom linters (Codex-generated, of course!) and structural tests.
智能体在具有严格边界和可预测结构的环境中最为高效,因此我们围绕一套刚性的架构模型来构建应用。每个业务领域被划分为固定的若干层,依赖方向受到严格校验,允许的边也有限。这些约束由自定义 linter(当然是 Codex 生成的!)和结构性测试机械化地执行。
The diagram below shows the rule: within each business domain (e.g. App Settings), code can only depend “forward” through a fixed set of layers (Types → Config → Repo → Service → Runtime → UI). Cross-cutting concerns (auth, connectors, telemetry, feature flags) enter through a single explicit interface: Providers. Anything else is disallowed and enforced mechanically.
下图展示了这条规则:在每个业务领域(例如 App Settings)内,代码只能沿固定的一组层“向前”依赖(Types → Config → Repo → Service → Runtime → UI)。横切关注点(auth、connectors、telemetry、feature flags)只能通过一个显式接口进入:Providers。其他任何依赖都被禁止,并由机械手段强制执行。
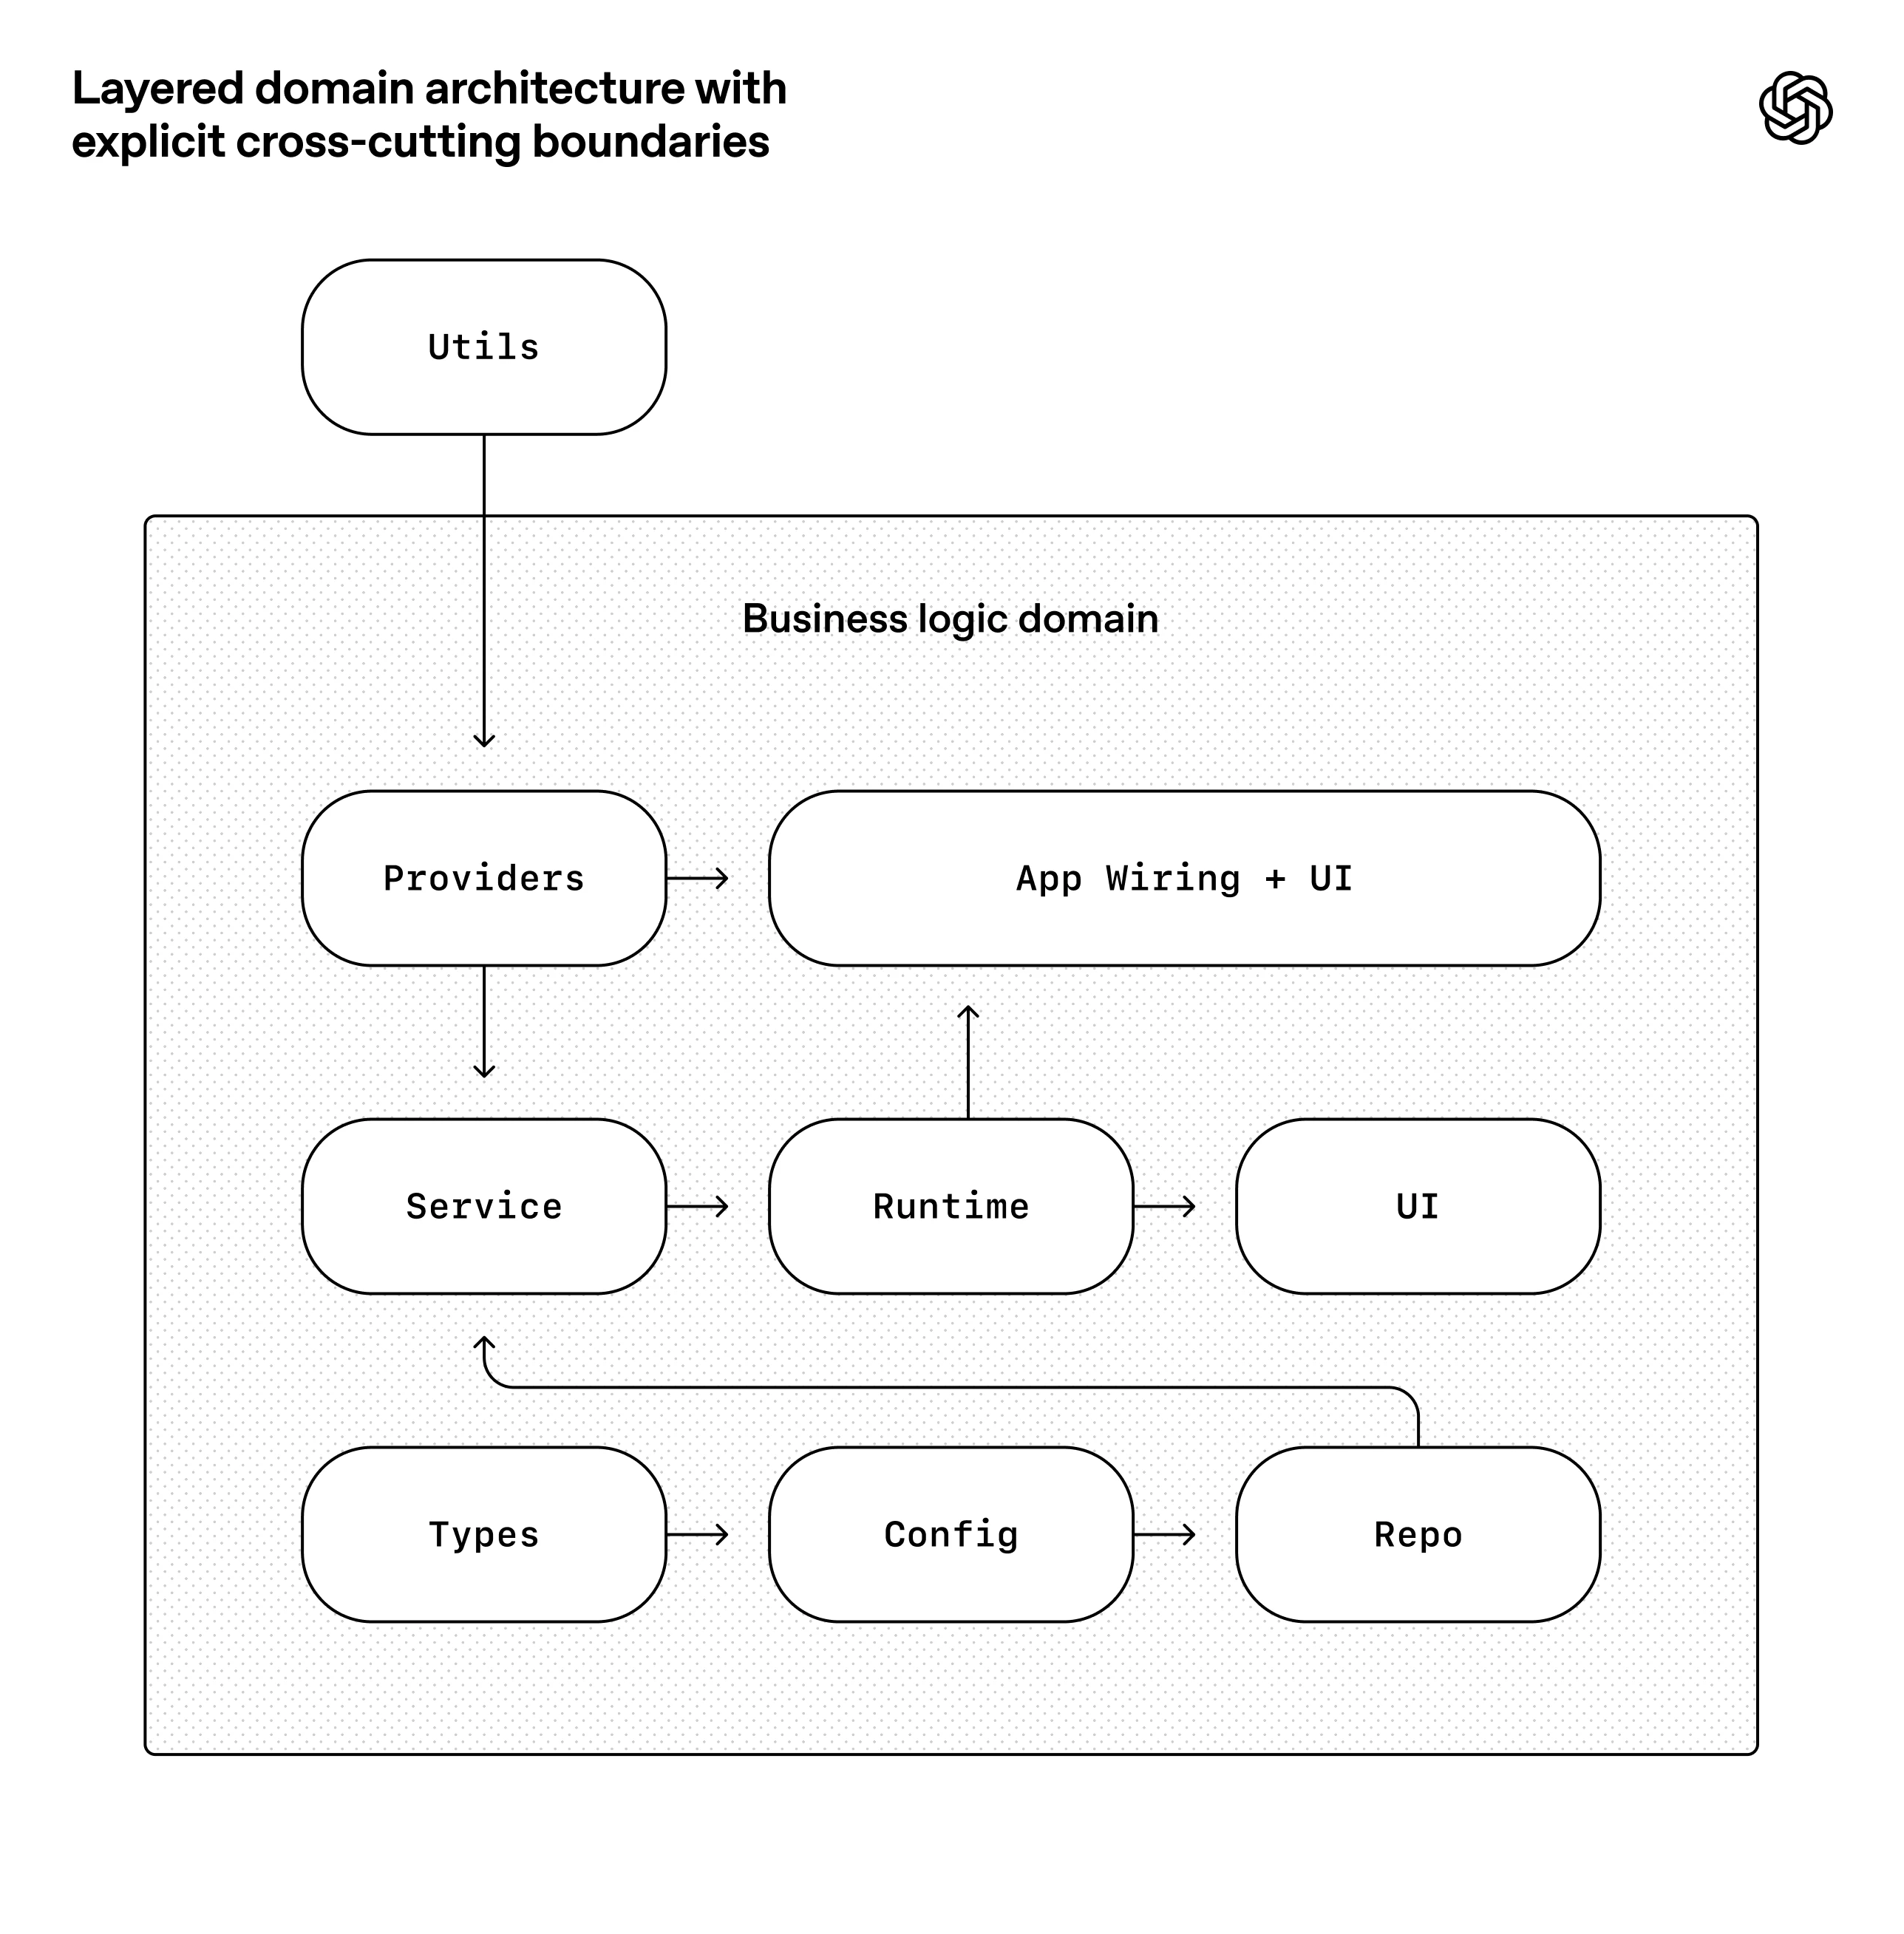
This is the kind of architecture you usually postpone until you have hundreds of engineers. With coding agents, it’s an early prerequisite: the constraints are what allows speed without decay or architectural drift.
这类架构通常要等到你有数百名工程师时才会考虑。而有了编码智能体,它变成了一个早期前提条件:正是这些约束,让速度得以维持,而不至于衰退或出现架构漂移。
In practice, we enforce these rules with custom linters and structural tests, plus a small set of “taste invariants.” For example, we statically enforce structured logging, naming conventions for schemas and types, file size limits, and platform-specific reliability requirements with custom lints. Because the lints are custom, we write the error messages to inject remediation instructions into agent context.
在实践中,我们用自定义 linter 和结构性测试来执行这些规则,外加一小组“品味不变量”。例如,我们通过自定义 lint 静态强制结构化日志、schema 与类型的命名约定、文件大小限制,以及平台特定的可靠性要求。由于这些 lint 是自定义的,我们会编写错误信息,把修复指令注入智能体的上下文。
In a human-first workflow, these rules might feel pedantic or constraining. With agents, they become multipliers: once encoded, they apply everywhere at once.
在以人为先的工作流中,这些规则可能会显得迂腐或令人拘束。而对智能体来说,它们是倍增器:一旦被编码,就会同时作用于所有地方。
At the same time, we’re explicit about where constraints matter and where they do not. This resembles leading a large engineering platform organization: enforce boundaries centrally, allow autonomy locally. You care deeply about boundaries, correctness, and reproducibility. Within those boundaries, you allow teams—or agents—significant freedom in how solutions are expressed.
与此同时,我们对约束在何处重要、何处不重要保持明确。这类似于领导一个大型工程平台组织:在中心强制边界,在本地允许自治。你非常在意边界、正确性和可复现性。在这些边界之内,你给团队——或智能体——很大的自由去表达解决方案。
The resulting code does not always match human stylistic preferences, and that’s okay. As long as the output is correct, maintainable, and legible to future agent runs, it meets the bar.
由此产生的代码并不总是符合人类的风格偏好,这没关系。只要输出是正确的、可维护的,并且对未来的智能体运行是可理解的,它就达到了标准。
Human taste is fed back into the system continuously. Review comments, refactoring pull requests, and user-facing bugs are captured as documentation updates or encoded directly into tooling. When documentation falls short, we promote the rule into code
人类的品味会持续反馈到系统中。评审意见、重构 pull request 和用户可见的缺陷,都会被记录为文档更新,或直接编码进工具中。当文档不足以表达时,我们就把规则提升到代码层面。
Throughput changes the merge philosophy
吞吐量改变了合并哲学
As Codex’s throughput increased, many conventional engineering norms became counterproductive.
随着 Codex 的吞吐量提升,许多常规工程规范反而变得适得其反。
The repository operates with minimal blocking merge gates. Pull requests are short-lived. Test flakes are often addressed with follow-up runs rather than blocking progress indefinitely. In a system where agent throughput far exceeds human attention, corrections are cheap, and waiting is expensive.
仓库运行在极少的阻塞式合并门禁之下。Pull request 的生命周期很短。测试的偶发失败通常通过后续重跑解决,而不是无限期阻塞进度。在一个智能体吞吐量远超人类注意力的系统里,纠错成本很低,而等待的代价很高。
This would be irresponsible in a low-throughput environment. Here, it’s often the right tradeoff.
在低吞吐量环境中,这样做是不负责任的。而在这里,它往往是正确的取舍。
What “agent-generated” actually means
“智能体生成”到底意味着什么
When we say the codebase is generated by Codex agents, we mean everything in the codebase.
当我们说这个代码库由 Codex 智能体生成时,我们指的是代码库中的一切。
Agents produce:
智能体产出:
Product code and tests
CI configuration and release tooling
Internal developer tools
Documentation and design history
Evaluation harnesses
Review comments and responses
Scripts that manage the repository itself
Production dashboard definition files
产品代码和测试
CI 配置和发布工具
内部开发者工具
文档和设计历史
评估 harness(评估工装)
评审意见和回应
管理仓库本身的脚本
生产环境仪表盘的定义文件
Humans always remain in the loop, but work at a different layer of abstraction than we used to. We prioritize work, translate user feedback into acceptance criteria, and validate outcomes. When the agent struggles, we treat it as a signal: identify what is missing—tools, guardrails, documentation—and feed it back into the repository, always by having Codex itself write the fix.
人类始终在回路中,但工作在我们过去不曾处的抽象层级上。我们排定优先级,把用户反馈转化为验收标准,并验证结果。当智能体遇到困难时,我们把它视为一个信号:识别缺了什么——工具、护栏、文档——并把它反馈回仓库,而且始终是由 Codex 自己来写修复。
Agents use our standard development tools directly. They pull review feedback, respond inline, push updates, and often squash and merge their own pull requests.
智能体直接使用我们的标准开发工具。它们拉取评审反馈、在行内回应、推送更新,并且经常自行 squash 并合并自己的 pull request。
Increasing levels of autonomy
不断提升的自主性
As more of the development loop was encoded directly into the system—testing, validation, review, feedback handling, and recovery—the repository recently crossed a meaningful threshold where Codex can end-to-end drive a new feature.
随着开发回路中越来越多的环节被直接编码进系统——测试、验证、评审、反馈处理和恢复——仓库最近跨过了一个有意义的门槛:Codex 可以端到端地驱动一个新功能。
Given a single prompt, the agent can now:
给定一个提示,智能体现在可以:
Validate the current state of the codebase
Reproduce a reported bug
Record a video demonstrating the failure
Implement a fix
Validate the fix by driving the application
Record a second video demonstrating the resolution
Open a pull request
Respond to agent and human feedback
Detect and remediate build failures
Escalate to a human only when judgment is required
Merge the change
验证代码库的当前状态
复现一个被报告的缺陷
录制一段演示该故障的视频
实现修复
通过驱动应用来验证修复
录制第二段演示问题已解决的视频
发起 pull request
回应智能体和人类的反馈
检测并修复构建失败
仅在需要判断时升级给人类
合并改动
This behavior depends heavily on the specific structure and tooling of this repository and should not be assumed to generalize without similar investment—at least, not yet.
这一行为高度依赖本仓库特定的结构和工具链,不应假设在没有类似投入的情况下可以普遍适用——至少目前还不能。
Entropy and garbage collection
熵与垃圾回收
Full agent autonomy also introduces novel problems. Codex replicates patterns that already exist in the repository—even uneven or suboptimal ones. Over time, this inevitably leads to drift.
完全的智能体自主也带来了新问题。 Codex 会复制仓库中已经存在的模式——即使这些模式并不均衡或并非最优。随着时间推移,这不可避免地导致漂移。
Initially, humans addressed this manually. Our team used to spend every Friday (20% of the week) cleaning up “AI slop.” Unsurprisingly, that didn’t scale.
起初,人类手动处理这个问题。我们团队过去每周五(占一周工作时间的 20%)都在清理“AI 垃圾”。不出所料,这种方式无法扩展。
Instead, we started encoding what we call “golden principles” directly into the repository and built a recurring cleanup process. These principles are opinionated, mechanical rules that keep the codebase legible and consistent for future agent runs. For example: (1) we prefer shared utility packages over hand-rolled helpers to keep invariants centralized, and (2) we don’t probe data “YOLO-style”—we validate boundaries or rely on typed SDKs so the agent can’t accidentally build on guessed shapes. On a regular cadence, we have a set of background Codex tasks that scan for deviations, update quality grades, and open targeted refactoring pull requests. Most of these can be reviewed in under a minute and automerged.
于是,我们开始把我们称之为“黄金原则”的东西直接编码进仓库,并建立了一套周期性的清理流程。这些原则是有明确倾向的机械化规则,目的是让代码库对未来的智能体运行保持可理解性和一致性。例如:(1) 我们偏好共享工具包而非手写辅助函数,以集中维护不变量;(2) 我们不以“YOLO 式”方式探测数据——我们验证边界或依赖带类型的 SDK,这样智能体就不会意外地基于猜测的数据形状进行构建。我们会定期运行一组后台 Codex 任务,扫描偏离情况、更新质量评分,并提交有针对性的重构 pull request。其中大多数可以在一分钟内评审完并自动合并。
This functions like garbage collection. Technical debt is like a high-interest loan: it’s almost always better to pay it down continuously in small increments than to let it compound and tackle it in painful bursts. Human taste is captured once, then enforced continuously on every line of code. This also lets us catch and resolve bad patterns on a daily basis, rather than letting them spread in the code base for days or weeks.
这起到了类似垃圾回收的作用。技术债就像一笔高息贷款:持续以小额增量偿还,几乎总是比让它复利增长、再痛苦地集中解决要好。人类的品味被捕获一次,然后持续地在每一行代码上强制执行。这也让我们能够按天发现并解决坏模式,而不是让它们在代码库中扩散数天或数周。
What we’re still learning
我们仍在学习的东西
This strategy has so far worked well up through internal launch and adoption at OpenAI. Building a real product for real users helped anchor our investments in reality and guide us towards long-term maintainability.
到目前为止,这一策略在 OpenAI 内部的发布与采用过程中运作良好。为真实用户构建真实产品,帮助我们把投入锚定在现实中,并引导我们走向长期可维护性。
What we don’t yet know is how architectural coherence evolves over years in a fully agent-generated system. We’re still learning where human judgment adds the most leverage and how to encode that judgment so it compounds. We also don’t know how this system will evolve as models continue to become more capable over time.
我们尚不清楚的是:在一个完全由智能体生成的系统中,架构一致性会如何随时间演化。我们也仍在学习人类判断在何处能带来最大的杠杆,以及如何把这种判断编码进去以形成复利。我们同样不知道,随着模型能力持续提升,这一系统将如何演化。
What’s become clear: building software still demands discipline, but the discipline shows up more in the scaffolding rather than the code. The tooling, abstractions, and feedback loops that keep the codebase coherent are increasingly important.
已经清晰的是:构建软件依然需要纪律,但纪律更多体现在脚手架而不是代码上。保持代码库一致性的工具、抽象和反馈回路正变得越来越重要。
Our most difficult challenges now center on designing environments, feedback loops, and control systems that help agents accomplish our goal: build and maintain complex, reliable software at scale.
我们现在最困难的挑战,集中在设计环境、反馈回路和控制系统,以帮助智能体实现我们的目标:大规模地构建和维护复杂、可靠的软件。
As agents like Codex take on larger portions of the software lifecycle, these questions will matter even more. We hope that sharing some early lessons helps you reason about where to invest your effort so you can just build things.
随着 Codex 这样的智能体承担软件生命周期中更大比例的工作,这些问题会变得更加重要。我们希望分享一些早期经验,能帮助你思考该把精力投向何处,从而真正把东西做出来。